RTX 4090 Tensor Unlock to 331.6 TF/s: Open-Source Patch Cuts the Half-Rate Cap, but Does Your AI Workload Really Double in Speed?
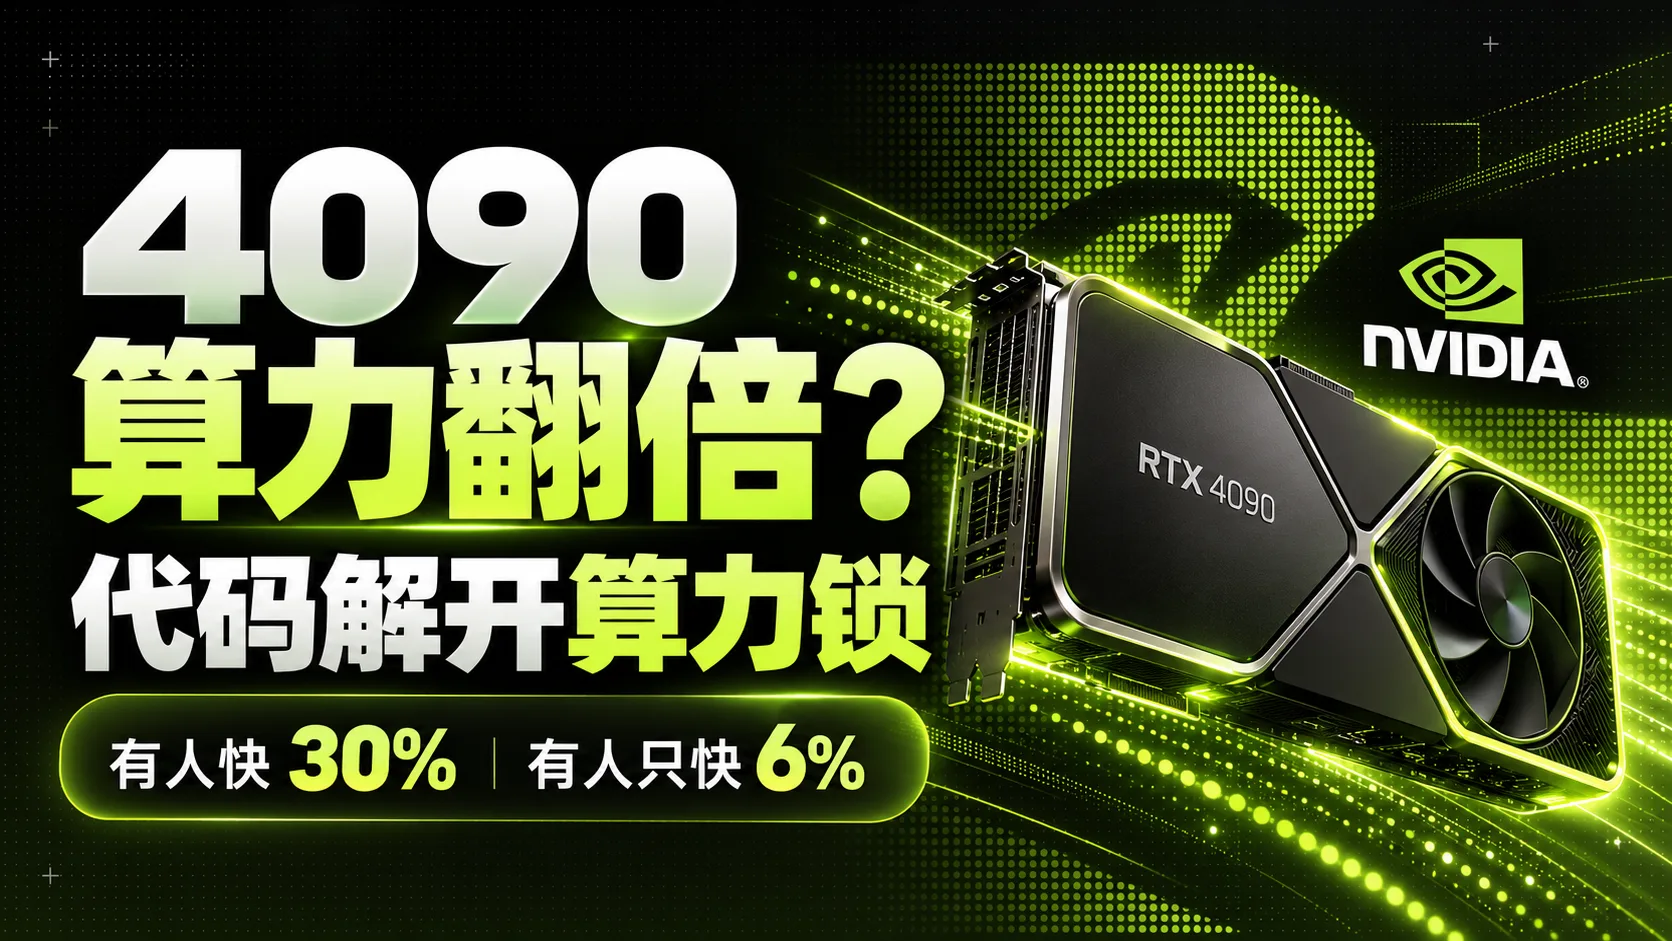
实测拆解社区热议的 NVIDIA 消费卡半速 AI 算力解锁方案:开源代码在开机 Linux initramfs 阶段切换固件内部档位,令 RTX 4090 特定 Tensor 指令吞吐从 165.6 飙升至 331.6 TF/s。本期深度评测 LLM 预填充 vs 解码阶段差异、长文本与量化 MoE 的搬运瓶颈、生图与 AI 视频全流程耗时摊薄、游戏帧率真相、底层非 vBIOS 机制与避坑验收指南。
A deep-dive benchmark and architectural analysis of the viral open-source NVIDIA consumer GPU half-rate unlock patch. By toggling internal firmware registers during early Linux initramfs boot, specific Tensor instruction throughput on the RTX 4090 jumps from 165.6 to 331.6 TF/s. We unpack LLM prefill vs. decode behavior, memory-shuffling bottlenecks in quantized MoEs, end-to-end dilution across image and video pipelines, gaming FPS realities, non-vBIOS mechanics, and hard verification guidelines.
大家好 我是为什么叫QQ
Hello everyone, I'm WhyCallQQ.
你已经买到手的NVIDIA显卡
The NVIDIA graphics card already sitting in your rig—
部分AI计算路径可能一直被配置在半速
parts of its AI compute pipeline might have been running at half speed all along.
没有超频 没有修改原版驱动
No overclocking, no modified proprietary drivers—
一段开源代码在开机时把它打开了:
just an open-source script run at boot that unlocked it:
RTX 4090的特定指令吞吐
throughput on specific RTX 4090 instructions
从165.6提高到331.6TF/ s 接近两倍
jumped from 165.6 to 331.6 TF/s, nearly doubling.
代码怎么碰到普通软件改不了的设置?
How could open-source code touch settings ordinary software cannot reach?
NVIDIA又为什么这样配置?更关键的是 解锁之后
Why did NVIDIA configure it this way in the first place? And more importantly, once unlocked,
你的LLM 生图和视频项目真能少等一半吗?
does your LLM, image generation, or video workload really finish in half the time?
社区里 有人报告任务时间减少约30%
Across the community, some report job wall-clock time dropping by about 30%;
有人只快约6% 也有人几乎没变化
others see only a 6% boost, and some notice almost no difference at all.
同一把钥匙 结果相差这么大
With the exact same key in hand, why are the real-world results so radically different?
答案显然藏在“翻倍”两个字之外
The answer clearly lies far beyond the headline buzzword of 'doubling speed'.
这期就沿着这四层问题往下查
In this episode, we'll peel back the layers through four core questions:
看看锁在哪里 谁又能真正受益
where the lock is placed, and who actually stands to benefit.
先按使用场景给答案
Let's put the conclusions by use case up front.
运行LLM时 长文档 RAG和批量处理更值得试
For LLM inference, long documents, RAG, and batch processing are well worth testing,
因为读入提示词的阶段可能明显提速;
because the prompt ingestion phase can see significant acceleration;
日常聊天逐字输出的速度 很多时候几乎不变
meanwhile, token-by-token generation in casual chats stays virtually unchanged.
图像生成有潜在收益
Image generation shows promising potential:
部分注意力内核已经出现较大提升
certain attention kernels already exhibit substantial speedups,
但完整生图能省多少时间 还取决于模型和分辨率
yet total end-to-end time saved still depends on your specific model and resolution.
AI视频计算量更大 理论上更值得关注
AI video entails much heavier compute, making it theoretically even more compelling,
目前公开端到端对照却很少
though rigorous end-to-end public benchmarks remain scarce.
游戏玩家可以暂时关掉安装教程
Gamers, on the other hand, can close the setup tutorials for now:
现有材料没有可靠帧率提升
available benchmark data shows zero reliable frame rate improvements.
还有一条很实际:
There is also one very practical reality:
它不会增加显存 原本装不下的模型
it does not increase VRAM; models that didn't fit into memory before
解锁后依然装不下
will still not fit after unlocking.
它解决的是部分计算速度 没有解决模型容量
It unlocks partial computational throughput—it does not expand model capacity.
这里要分清事实和推测
Here we must strictly distinguish facts from speculation.
公开测试能确认
Public reproducible tests confirm
部分消费卡的特定AI计算路径被配置在半速
that specific AI compute paths on certain consumer cards are configured at half-rate,
代码可以把速度选择改回去;
and open-source code can toggle that speed register back.
NVIDIA却没有公开说明这套配置的设计动机
Yet NVIDIA has never publicly disclosed the architectural rationale behind this configuration.
消费级与专业级产品存在性能和功能分层
Consumer and professional tier products have always featured segmented tiers;
商业区隔是一个合理解释
market segmentation is certainly a reasonable explanation,
功耗 验证范围与可靠性要求也可能影响配置
while power draw, QA validation scope, and silicon reliability may also factor in.
没有官方材料
Without official documentation,
就不能把某一种推测写成厂商承认的答案
we cannot treat any single hypothesis as NVIDIA's admitted stance.
真正让社区炸开的 是硬件已经卖给用户
What truly set the community ablaze is that this hardware was bought and paid for,
隐藏速率又能被开源代码改变
yet a throttled rate can now be altered by open code.
它同时碰到了免费性能 产品分层和用户控制权
It strikes at the intersection of free performance, product segmentation, and user ownership,
争议自然来了
so fierce controversy was inevitable.
对普通开发者
For everyday developers,
最实际的用途是缩短本地AI的等待时间
the most practical goal is cutting down idle wait time on local AI tasks.
有人用3060跑nanochat训练 报告约6% 的提速;
Someone training nanochat on an RTX 3060 reported roughly a 6% speedup;
四张3090的推理个案 实际收益约7% 到8%;
a quad-3090 inference setup saw real gains around 7% to 8%;
改装48GB 4090的用户报告
while a user with a modded 48GB RTX 4090 reported
一次工作任务墙钟时间减少约30%
a real-world workload wall-clock reduction of roughly 30%.
这些数字差异很大 恰恰说明它适合按项目评估
These widely divergent figures prove that gains must be evaluated per workload,
不能按显卡型号承诺
rather than promised across the board by GPU model.
个人训练小模型 处理长文本提示词 批量跑生成任务
Training small models locally, processing long prompts, or running batch generations
可能感受到变化
are where you are most likely to feel a tangible difference—
尤其是任务每天重复运行时
especially when pipelines run repeatedly every single day,
即使个位数收益也能积少成多
where even single-digit percentage gains compound into substantial savings.
只是偶尔问几句 主要玩网游
If you just chat occasionally and primarily play online games,
收益很可能不值得维护成本
the negligible gains will likely never justify the maintenance hassle.
显存容量 多卡互联和视频编码能力
VRAM capacity, multi-GPU interconnects, and NVENC video encoders
也不会被这次解锁改变
remain completely untouched by this patch.
把LLM想成先读题 再写答案
Think of LLM inference as reading the question first, then writing the answer.
读题叫预填充 模型一次性处理整段提示词
Reading is prefill: the model processes the entire prompt in one go,
包含大量矩阵计算;
dominated by heavy dense matrix multiplications.
写答案叫解码 小批量使用时经常要反复读取权重
Writing is decode: at small batch sizes, weights must be repeatedly fetched from memory,
更容易卡在显存带宽
making it inherently bottlenecked by memory bandwidth.
上游一份3090用户报告里
In one upstream RTX 3090 benchmark report,
27B BF16模型的预填充吞吐提高约33%
prefill throughput on a 27B BF16 model increased by about 33%,
首token等待时间下降约24% 解码只提高1.2%
time-to-first-token dropped by ~24%, while decode speed only crept up by 1.2%.
所以长文档总结
Therefore, long-document summarization,
代码库问答 批量请求更值得测试
codebase Q&A, and high-concurrency batch requests are the sweet spots to benchmark;
首字可能更快出现
the first token will appear noticeably faster.
RAG把检索到的资料塞进提示词后
When RAG injects retrieved context chunks into your prompt,
输入也会变长 同样值得观察这一阶段
the context window expands, making this phase equally primed for gains.
若你主要嫌后续文字生成慢
If your primary complaint is sluggish token generation speed afterward,
这次解锁未必能解决问题
this unlock will do virtually nothing for you.
换量化 降低上下文或优化KV缓存可能更直接
Switching to aggressive quantization, pruning context, or optimizing KV cache is far more effective.
同样叫LLM
Even under the umbrella of LLMs,
不同模型和运行方式可能得到完全不同的收益
different model architectures and runtime setups produce wildly divergent outcomes.
另一份3090报告里 量化MoE模型处理16K输入时
In another RTX 3090 report, running a quantized MoE model with 16K input context
预填充提高14.4%;
yielded a 14.4% prefill improvement;
输入拉长到约32K
but once context stretched to around 32K,
专家权重从内存搬运成了主要耗时 提升又消失了
shuffling expert weights across host memory became the dominant bottleneck, wiping out the gain.
INT8 INT4走的计算路径也可能不同
INT8 and INT4 quantization may also utilize completely different instruction paths,
不能拿FP16的成绩直接套过来
so FP16/BF16 benchmark numbers cannot be naively generalized.
你可以先观察自己的服务:
Inspect your own deployment profile first:
长提示词占比高 batch较大 矩阵计算耗时突出
if long prompts dominate, batch sizes are large, and matrix math is the bottleneck,
就更有试验价值
it is definitely worth putting to the test.
模型经常换 上下文很短 权重
If you frequently switch models with short context, and weights
还要在内存和显存之间来回搬
must constantly be swapped back and forth between RAM and VRAM,
优先解决这些问题 收益会更明确
solving those structural overheads first will yield far clearer payoffs.
量化能省显存 却不保证命中这次加速路径
Quantization saves VRAM, but does not guarantee hitting this specific accelerated instruction path—
两个优化目标要分开
keep those two optimization targets strictly decoupled.
图像生成不是一整块完全相同的计算
Image generation is not a monolithic compute block either.
提示词编码 注意力 主网络
Text encoder, cross-attention, diffusion backbone,
VAE解码和保存图片依次耗时
VAE decoding, and PNG compression all consume distinct stages of time.
这次解锁只可能影响其中一部分
This unlock can only accelerate a specific subset of those operations.
上游3090个案里
In an upstream RTX 3090 case study,
FlashAttention 2内核提高约53% 到54%
FlashAttention 2 kernel throughput surged by roughly 53% to 54%,
说明生图相关计算确实有受益空间;
confirming that diffusion attention primitives have genuine headroom for gains.
同一份报告还记录了Z
The same report also recorded that Z-Image Turbo
- Image Turbo解锁后每张4.89秒
clocked in at 4.89 seconds per image post-unlock,
却没提供解锁前成绩 无法算出完整提速
without providing baseline pre-unlock numbers, making the net speedup impossible to calculate.
高分辨率 大批量 注意力占比高的任务更值得测
High-resolution, large batch, attention-heavy jobs are the best candidates to profile.
VAE或磁盘导出占比高时 整轮变化可能很小
When VAE decoding or disk I/O accounts for a large fraction, overall wall-clock change will be slim.
现阶段别承诺生图时间减半
At this stage, never promise that image generation times will cut in half;
用自己的固定提示词跑一次对照更可靠
running a controlled baseline with your own fixed prompts is far more reliable.
固定随机种子和采样步数
Fix your random seed and sampling steps,
连续跑多张 再比较平均时间与显存占用
generate a consistent batch, and compare average latency and peak VRAM allocation.
AI视频可以看成连续处理许多帧
AI video can be understood as sequentially generating dozens of coherent frames,
还要维护时间和空间上的关系
while enforcing complex temporal and spatial cross-attention.
注意力与主网络计算往往更重
Temporal attention and backbone compute are significantly heavier,
因此 只要模型命中被加速的路径
so as long as the workload hits the unthrottled instruction paths,
节省的时间可能比单张图片更有感
the absolute time saved could feel much more substantial than in still images.
不过 帧数增加也会放大显存读写
However, higher frame counts also drastically multiply VRAM bandwidth,
VAE解码 数据搬运和编码导出的成本
VAE temporal decoding, cross-device data transfers, and video encoding costs.
后面的环节不会同步提速
Those downstream stages will not accelerate in tandem.
现有40系仓库没有公开完整的视频生成前后对照
No current RTX 40-series repo has published comprehensive before-and-after video generation comparisons;
上游个案也只能证明特定机器曾经跑通
upstream cases only prove that specific rigs ran successfully without crashing.
做视频项目的人值得保持关注
Creators running video generation pipelines should certainly keep a close eye on this,
尤其是长视频和批量任务
particularly for long-form clips and batch jobs,
但目前最负责任的结论是:
yet the most responsible conclusion today is simple:
有技术潜力 实际百分比仍要等你的模型实测
there is clear theoretical potential, but actual percentage gains must await your own benchmarks.
普通转码和视频导出属于另一类任务
Standard video transcoding and editing exports belong to dedicated NVENC silicon—
也别把生成速度套到编码速度上
never conflate diffusion generation throughput with media encoder speed.
如果你主要关心游戏 这期结论很简单:
If gaming performance is your primary concern, the takeaway is straightforward:
暂时没有可靠证据证明帧率会明显提高
there is currently zero reliable evidence showing measurable FPS gains.
游戏画面涉及CUDA Core
Game rendering hinges on standard CUDA cores,
光追单元 显存 CPU和驱动调度
RT cores, VRAM bandwidth, CPU bottlenecks, and DirectX/Vulkan driver scheduling.
这次变化集中在部分Tensor指令
This patch specifically unthrottles a targeted subset of Tensor core instructions;
标量FP32对照也没有提速
scalar FP32 benchmarks show zero speedup.
即便DLSS等功能会用到Tensor Core
Even though features like DLSS leverage Tensor cores,
也没有公开对照证明解锁后画质档位不变
there are no verified comparative runs proving that at identical image quality presets
帧率还能提高
frame rates actually increase.
为了游戏去修改启动链 风险和收益很不相称
Tampering with your system boot chain purely for games carries completely disproportionate risks.
它更适合被看作本地AI与计算项目的实验工具
It is best treated as an experimental sandbox tool for local AI and compute workloads.
等出现同卡 同驱动 同场景的重复帧率测试
Wait until rigorous, peer-reviewed tests emerge using identical cards, drivers, and game scenes
再讨论游戏价值也不迟
before reassessing its gaming relevance.
很多人最难理解的是
What many find hardest to grasp intuitively is:
指令接近两倍 完整程序为何只快一点
if raw instruction throughput nearly doubled, why does the application only run slightly faster?
把GPU想成一家工厂:计算单元提高了加工速度
Picture a GPU as a modern factory: the processing machines doubled their machining speed,
仓库送货 工序交接和包装出货却没变
but raw material warehousing, conveyor handoffs, and packaging dispatch remained unchanged.
总交付时间就不会减半
Naturally, the total delivery time cannot magically drop by half.
4090的独立配对测试里
In independent paired tests on the RTX 4090,
cu BLAS矩阵乘随形状出现
cuBLAS GEMM matrix operations showed varying gains depending on matrix dimensions:
约12%到34.4%的FP 16收益 一组BF16还几乎没变
roughly 12% to 34.4% FP16 throughput gains, while one BF16 configuration showed almost zero change.
再举一个简单例子
Consider a simple hypothetical scenario:
100毫秒任务里只有70毫秒能加速
out of a 100ms pipeline, only 70ms consists of code eligible for acceleration.
即使这部分快两倍 剩余30毫秒照跑
Even if that 70ms portion speeds up 2x down to 35ms, the remaining 30ms runs at normal speed;
总耗时仍是65毫秒
total runtime drops only to 65ms.
应用收益被其他环节摊薄 是正常结果
Having headline compute gains diluted by unaccelerated stages is classic Amdahl's Law at work.
所以做优化前先看耗时分布
Profiling your latency breakdown before optimizing
比盯着一个漂亮的峰值数字更有用
is far more insightful than fixating on a flashy peak TFLOPS statistic.
它做的事情可以简化为:
What the patch actually does can be distilled into simple terms:
开机早期 在NVIDIA官方驱动接管显卡之前
during early boot, before NVIDIA's official proprietary driver initializes the GPU,
通过固件权限修改一项内部速度配置
it utilizes firmware-level access to flip an internal operational rate configuration register,
然后重启显卡功能 让原版驱动继续工作
then triggers a GPU subsystem reset so the unmodified stock driver takes over seamlessly.
没有增加物理核心 也没有提高功耗上限
No physical cores are added, power limits remain unchanged,
OTP熔丝读数同样没变
and on-die OTP hardware fuses are completely untouched.
对使用者来说 模型代码通常不用改;
From a developer's perspective, PyTorch and CUDA model code requires zero alterations;
真正的门槛在Linux启动环境
the real barrier lies in configuring the Linux bootloader and initramfs environment.
模块要进入initramfs 首次尝试需要冷启动
The kernel module must be packaged into initramfs, and initial probing requires a full cold reboot.
部分卡还要单独实验开关
Certain board revisions may even require manual toggling of individual parameter flags.
它没有重刷vBIOS 恢复时可以撤掉启动参数
Because it avoids flashing vBIOS ROMs, rolling back is as easy as removing the boot argument;
但启动失败和兼容性问题仍要自己处理
nevertheless, kernel panics and PCIe boot hangs must still be diagnosed on your own.
它更像给硬件切换运行档位
It acts like switching the hardware into an unthrottled performance tier,
并非普通的CUDA参数优化
rather than tuning runtime CUDA launch configurations.
理解到这一层 已经足够判断使用成本
Grasping this operational model is enough to weigh the risk-reward tradeoff,
不必先钻进寄存器和ROP细节
without needing to drown in proprietary register offsets or ROP architecture details.
社区里最有代表性的好评
The most widely praised advantage in the developer community
是终于不用跟着驱动版本维护补丁
is finally being freed from maintaining driver-specific patch sets across updates,
多卡环境也更容易管理
making multi-GPU clusters far simpler to administer.
支持消费卡做研究的人 直接把它称为很有价值;
Researchers championing consumer-grade hardware have hailed it as immensely valuable;
5090用户则在催更新
while prospective RTX 5090 buyers are already clamoring for updates.
质疑同样具体:有人指出收益集中在预填充
Skeptics bring equally grounded critiques: pointing out that speedups remain locked to prefill,
解码和真实服务可能只有个位数提升;
yielding only single-digit throughput improvements in live interactive serving;
有人担心功耗 散热与长期稳定性;
others voice concerns regarding transient power spikes, thermals, and silicon longevity;
还有人争论训练究竟受计算还是显存限制
while others debate whether real-world training is compute- or memory-bound.
好现象是 仓库保留了没提速的案例
Encouragingly, the open-source repository openly documents null-speedup cases,
社区也会追问量化 batch和上下文
and community members actively scrutinize quantization schemes, batch sizes, and context lengths.
作者也提醒 50系对应的
The project authors also cautioned that the RTX 50-series,
Blackwell换了启动流程与安全层 不能简单移植
built on Blackwell, introduces overhauled boot flows and hardware root-of-trust, preventing easy ports.
这样的讨论比清一色喜报更有用
This level of technical candor is far more valuable than unconditional hype,
因为大家正在把“能解锁”
as it shifts the conversation from merely 'can we unlock it?'
逐步变成“在哪些项目里值得解锁”
to the far more mature question: 'which specific workloads actually justify unlocking?'
如果你有一台可恢复的Linux测试机
If you have a dedicated Linux staging machine with snapshot recovery,
跑文本提示词推理 模型训练或批量生成
running prompt-heavy inference, fine-tuning, or offline batch generation,
而且已经确认瓶颈在计算 可以把它列入实验
and have validated that compute is your primary bottleneck, it is worth exploring.
3090等30系有较多上游报告
RTX 30-series GPUs like the 3090 have abundant upstream case studies,
4090有原始测试和独立机主复测;
and the 4090 boasts baseline author benchmarks alongside independent owner replications;
其他型号不能照着名称类推
other GPU SKUs cannot be assumed to work simply by model name.
先保存原始成绩
Always log your stock baseline metrics first,
再固定模型 参数和功耗做多轮对照
then hold your model weights, hyperparameters, and power caps constant across multi-run comparisons.
线上生产机 唯一工作机 只想即装即用的人
Live production servers, daily-driver workstations, and users seeking turnkey stability
不适合当第一批试验者
should definitely steer clear of early experimentation.
测试时保留同一提示词
Keep identical test prompts,
同一模型版本和全部重复结果 别只挑最快的一次
the exact same checkpoint, and record all replicate iterations rather than cherry-picking the fastest run.
项目成功日志也不等于业务提速
A clean kernel boot log does not equal an end-to-end business speedup:
模型结果正确 长时间稳定 实际耗时下降
numerical accuracy, sustained multi-hour stability, and measurable wall-clock reduction
三项都要验收 把建议压缩成一张选择表
must all be verified. Let's summarize the recommendations into a decision matrix:
长文档问答 rag 批量LLM请求
Long-document Q&A, RAG context injection, and batch LLM serving:
值得优先测试首token和预填充;
prioritize profiling time-to-first-token and prefill throughput.
日常短聊天 先测解码 别期待整体翻倍
Short interactive chat: profile decode speed, and do not expect total latency to halve.
本地生图和AI视频 可以按同一提示词
Local diffusion and AI video: benchmark across fixed prompts,
同一尺寸 同一帧数比较整轮耗时
identical image resolutions, and matched frame counts while comparing total duration,
同时记录各阶段 游戏先观望
logging each sub-stage separately. For gaming: hold off and observe.
模型装不下 先解决显存容量 解锁帮不上忙
If a model won't fit into VRAM, solve your memory capacity first—unlocking will not help.
对消费级卡用户 它的意义是让已有硬件在
For consumer GPU owners, its real significance is extracting untapped hardware surplus
部分AI项目里发挥更多价值 而非替代升级
across targeted AI projects—not replacing a true architectural upgrade.
更不建议仅凭这些个案买卡
Never make hardware purchasing decisions based solely on these anecdotal benchmarks,
支持范围和长期稳定性还没有走完验证
as hardware SKU support and long-term silicon reliability are still undergoing community testing.
你会用哪项任务做对照?评论区留下卡型和结果
Which workload will you benchmark against? Share your GPU model and numbers in the comments below.
感谢观看 如果这份判断帮你省下折腾时间
Thank you for watching! If this breakdown saved you hours of trial and error,
欢迎一键三连 我是为什么叫QQ 我们下期见
don't forget to like, bookmark, and subscribe. I'm WhyCallQQ—see you next time!
大家好 我是为什么叫QQ
Hello everyone, I'm WhyCallQQ.
实测拆解社区热议的 NVIDIA 消费卡半速 AI 算力解锁方案:开源代码在开机 Linux initramfs 阶段切换固件内部档位,令 RTX 4090 特定 Tensor 指令吞吐从 165.6 飙升至 331.6 TF/s。本期深度评测 LLM 预填充 vs 解码阶段差异、长文本与量化 MoE 的搬运瓶颈、生图与 AI 视频全流程耗时摊薄、游戏帧率真相、底层非 vBIOS 机制与避坑验收指南。