OpenAI Revealed Its Ad Stack but Hid the Formula: Inside ChatGPT's $1B Agentic Ad Engine
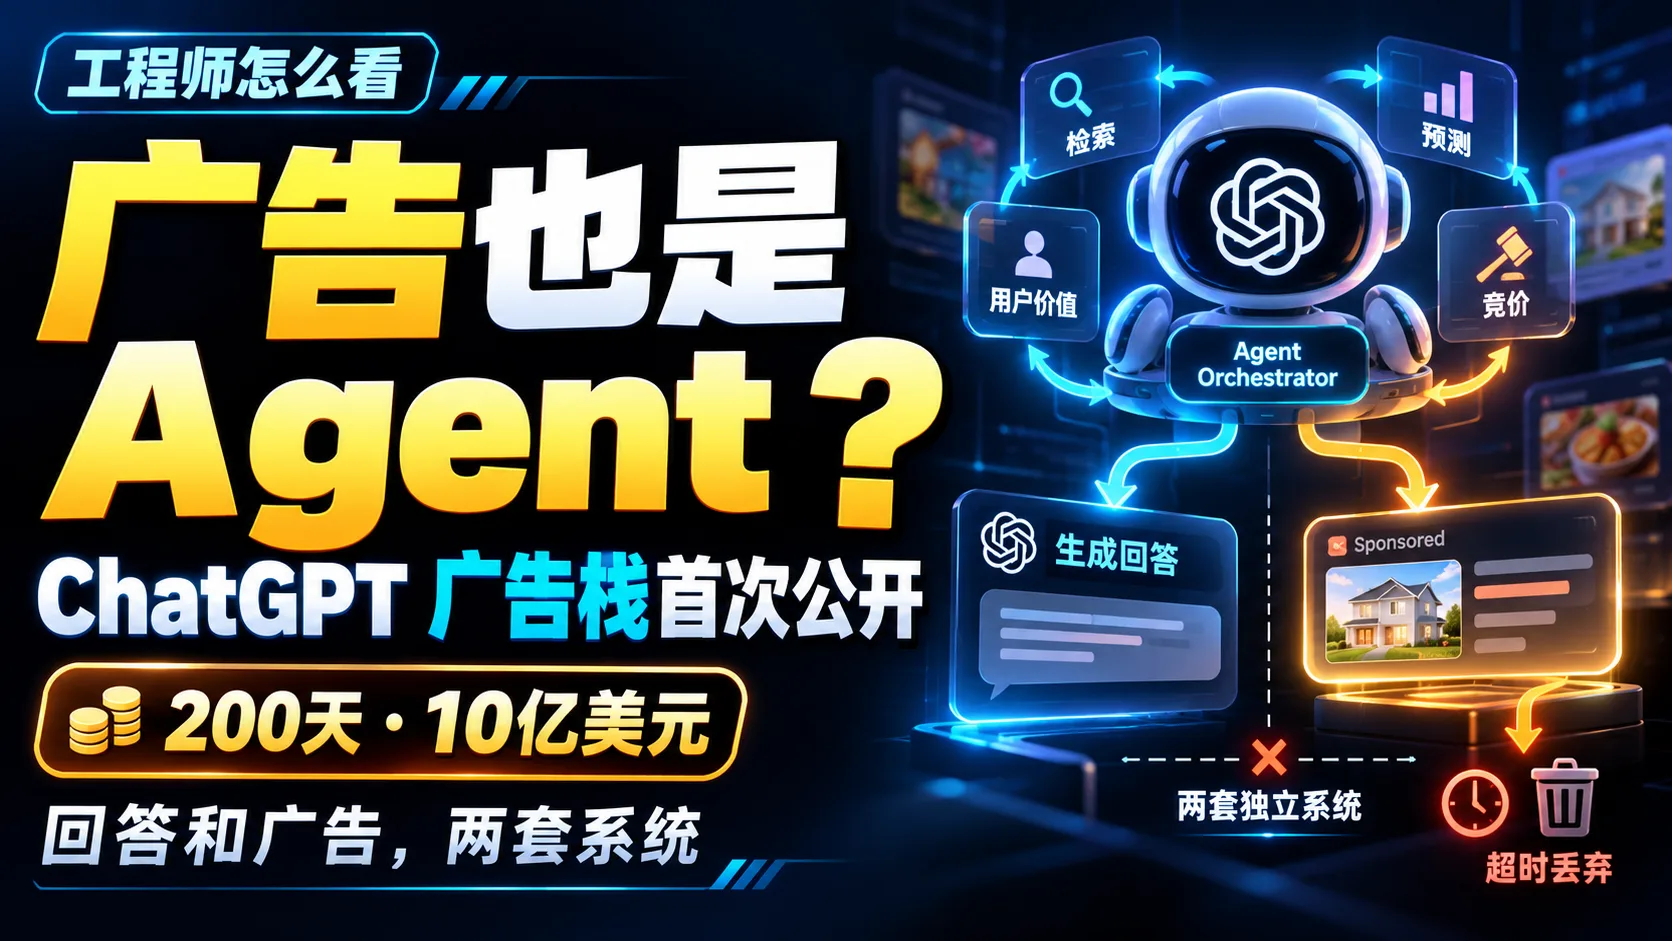
ChatGPT 的广告系统核心是一个后训练 LLM 在 agentic loop 里调用广告工具:理解多轮对话意图、生成语义查询、走 ANN 索引召回候选,经过两道资格与相关性漏斗后进入相关性加权二价拍卖,并通过最终上下文复核与超时直接丢弃机制保障主回答零延迟。
An engineering breakdown of OpenAI's conversational ad architecture—a post-trained LLM orchestrator operating in an agentic loop for multi-turn query rewriting, multi-index ANN retrieval, two-stage filtering funnels, relevance-weighted second-price auctions, and strict timeout dropping for zero-latency chat.
大家好 我是为什么叫QQ
Hello everyone, I'm WhyCallQQ.
你问ChatGPT 周末去优胜美地两天怎么安排
You ask ChatGPT how to plan a two-day weekend trip to Yosemite.
它逐字生成回答的同时
While it streams the response token by token,
后台另一个系统同时被唤醒
another system wakes up in the background at the exact same moment.
它读对话 理解意图 检索候选 过滤
It reads the conversation, infers intent, retrieves candidates, filters,
评分 竞价 在回答下方挂出一张Sponsored卡片
scores, runs an auction, and attaches a Sponsored card beneath the answer.
整套流程的编排者 是个LLM Agent
The orchestrator driving this entire pipeline is an LLM Agent.
2026年10月21日 OpenAI发了篇工程文章
On October 21, 2026, OpenAI published an engineering deep dive
首次完整公开这套广告栈 还披露了几个数字
unveiling this ad stack for the first time along with striking numbers:
广告上线不到200天
in less than 200 days since launch,
年化收入运行率到了10亿美元
annualized revenue run rate reached $1 billion,
累计超10万家广告主投过
with over 100,000 advertisers having run campaigns,
同一天覆盖扩到89个国家
and coverage expanding to 89 countries on the same day.
这期不聊OpenAI赚了多少钱 聊三个工程问题
Today we're not talking about OpenAI's revenue—we're tackling three engineering questions:
聊了十几轮 系统怎么判断你现在真正需要什么
1. After a dozen chat turns, how does the system know what you actually need right now?
让LLM调广告工具 比关键词匹配强在哪
2. Why does an LLM calling ad tools outperform traditional keyword matching?
广告能用你的对话上下文 又凭什么不影响回答
3. How can ads use your conversation context without biasing the chat response?
先交代背景
First, some architectural context.
传统广告系统是围绕一个个明确事件建的
Traditional ad systems are built around discrete, well-defined events:
你搜索一个关键词 或者打开一个网页
you search a keyword or load a webpage,
广告系统收到一次请求 检索候选 排序
the ad server receives a stateless request, retrieves candidates, ranks them,
竞价 展示 谷歌和Meta的机器都是这么转起来的
runs an auction, and renders the ad—that's how Google and Meta's engines run.
对话产品里没有这种干净的事件
Conversational products don't have clean, isolated events like that.
用户带着一个目标进来
A user arrives with a broad goal—
比如规划旅行 然后一轮一轮地聊
say, planning a trip—and chats back and forth over multiple turns.
意图在对话里慢慢长出来 还可能随时拐弯
Intent emerges gradually across turns and can pivot at any moment.
用传统架构硬接 等于把每条消息都当成独立请求
Bolting on a legacy ad stack means treating every message as an isolated request.
OpenAI在文章里列了这么干的几条风险
OpenAI highlighted several failure modes of that naive approach:
误读用户目标 广告出现得太早
misreading user goals, showing ads prematurely,
广告挡住用户正在做的事
interrupting the user's active task,
还有每次请求变化都重跑一遍流程 白白浪费算力
and wasting compute by re-running the entire pipeline on every minor turn.
所以他们的选择是 从头建一套广告栈
So they chose to architect a conversational ad stack from the ground up.
第一个关键点 广告会话是有状态的
Key Point 1: Ad sessions are stateful.
广告系统收到的是持续更新的对话流
The ad system ingests a continuously updated conversation stream,
它跨轮次记住并更新信息 跟着对话走
retaining and updating context across turns as the dialogue evolves.
文章给了一个很具体的例子
The paper gives a concrete example:
用户先问两天优胜美地行程怎么排
First, the user asks for a two-day Yosemite itinerary.
接着问下周会不会冷
Next, they ask if it will be cold next week.
第三轮突然问某个品牌的徒步鞋新品
On turn three, they suddenly ask about a specific brand's new hiking boots.
关键词匹配在这里基本抓瞎
Pure keyword matching is blind here—
三条消息字面上没什么共同词
the three messages share almost no literal keywords.
系统的做法是生成多条查询 保住意图的不同侧面
Instead, the system generates multiple queries to capture different facets of intent:
这段对话可能被改写成两条
this dialogue gets rewritten into two parallel queries—
一条是适合徒步旅行的鞋
one for cold-weather hiking footwear,
另一条是该品牌适合旅行的新品线
and another for that brand's new trail line.
这些查询还会持续迭代
These queries iterate continuously across turns
直到召回的广告足够有价值
until the retrieved ad candidates cross the value threshold.
你可以把它理解成 系统在持续回答一个问题
Think of the system as continuously answering a single question:
这个人此刻在商业上需要什么
'What is commercially useful to this person at this exact moment?'
第二个关键点 跑这套流程的核心
Key Point 2: The core engine driving this pipeline
是一个定制 经过后训练的前沿LLM
is a custom post-trained frontier LLM
官方管它叫orchestrator
that OpenAI calls the Orchestrator.
它工作在一个agentic loop里
It operates inside an agentic loop,
通过工具调用驱动整个广告链路
driving the entire ad pipeline via structured tool calls.
它能调的工具包括检索
Its toolset spans candidate retrieval,
资格检查 相关性估计 事件
eligibility checks, relevance estimation, event
预测 预算节奏 竞价和定价 但注意分工
prediction, budget pacing, auction, and pricing. But notice the division of labor:
orchestrator负责理解对话 生成查询 调用工具
the Orchestrator understands dialogue, rewrites queries, invokes tools,
提名哪些候选广告够格进入最终竞价
and nominates which ad candidates qualify for the final auction.
它不直接决定展示哪条广告 也不定价
It never directly picks the winning ad or sets the price.
真正的出价计算 预算节奏 质量调整排序和定价
Actual bid calculation, budget pacing, quality-adjusted ranking, and pricing
由专门的竞价系统完成 这个设计很典型
are executed by deterministic auction systems. This pattern is textbook:
让LLM做需要理解力的判断 让确定性系统管钱
let the LLM handle semantic judgment, and let deterministic code handle money.
管钱的环节 永远别让生成模型直接碰
Never let a generative model directly touch financial clearing.
编排准备好了查询 下一步是检索
Once the Orchestrator prepares the queries, the next stage is retrieval.
查询会被编码成高维语义向量
Queries are encoded into high-dimensional semantic embeddings
走进多个ANN索引做近似最近邻搜索
and dispatched across multiple ANN (Approximate Nearest Neighbor) indices
快速拉回一个刻意放宽的候选池
to rapidly pull back a deliberately broad candidate pool.
ANN求的是快 是足够好 是最优解的近似
ANN optimizes for low latency and 'good enough' recall rather than exact search—
召回阶段要的就是宽 后面再慢慢收窄
retrieval casts a wide net so downstream stages can narrow it down.
索引也不止一种
And there isn't just a single index:
文章提到 商品feed广告的索引在
the article notes that product-feed ad indices
取广告时会感知产品评论的正负面
incorporate customer review sentiment during retrieval,
这个约束对没有评论的普通广告就不存在
a constraint that doesn't apply to standard campaign ads without reviews.
不同检索策略拉回的候选 进入同一个合并候选池
Candidates from diverse retrieval strategies merge into a unified candidate pool
在相同的投放约束下竞争
to compete under the same delivery constraints.
到这一步 池子里装的是可能性
At this point, the pool holds raw possibilities,
离最终赢家还很远 候选池之后是两道闸
still far from a final winner. Next come two strict gates.
第一道是资格与安全过滤
Gate 1 is Eligibility and Safety Filtering:
创意和campaign是否在线 投放地域对不对
Are the creative and campaign active? Does geo-targeting match?
政策合不合规 预算还剩多少
Does it pass policy compliance? Is budget remaining?
投放节奏该不该现在花钱
Does budget pacing allow spend right now?
这条广告适不适合当前对话场景
Is the ad safe for the current conversation context?
还有同一个广告主的去重
Plus per-advertiser deduplication.
任何一项不过 直接出局 第二道是评分
Fail any single check and the candidate is eliminated immediately. Gate 2 is Scoring:
orchestrator调用一组评分系统
the Orchestrator invokes specialized scoring models
看语义相关性 预测互动概率
to evaluate semantic relevance, predict engagement probability,
查这条广告的历史表现
and inspect historical performance.
评分高的候选才有资格进竞价
Only high-scoring candidates earn a seat at the auction.
整条链路是一个逐级收窄的漏斗
The entire pipeline acts as a progressively narrowing funnel:
宽召回 严过滤 再评分
broad recall, strict filtering, then multi-model scoring.
这个结构你在搜索和推荐系统里见过无数次
You've seen this funnel structure countless times in search and recommender systems—
区别在于 漏斗每一级的开关 握在一个LLM手里
the difference is that an LLM holds the control switches at every stage.
漏斗尽头是竞价
At the bottom of the funnel sits the auction.
官方帮助文档的说法是 相关性加权的二价拍卖
OpenAI's documentation describes it as a relevance-weighted second-price auction.
二价拍卖的意思是 赢家支付的价格参考次高出价
Second-price means the winner pays based on the runner-up's bid,
你不用为自己的出价上限买单
so advertisers aren't penalized for bidding their true maximum value.
相关性加权的意思是 出价只是因子之一
Relevance-weighted means raw bid price is only one factor—
广告和对话的匹配质量同样进公式
how well the ad matches the conversation enters the ranking formula directly.
出价低但高度相关的广告
A lower-bidding but highly relevant ad
可以赢过出价高但匹配差的
can beat a high-bidding ad with poor contextual fit.
完整的定价公式没有公开 这一点要说明白
To be transparent, the exact pricing formula isn't publicly disclosed.
还有一个细节
There's one more crucial detail:
orchestrator会给竞价圈一个入场门槛
the Orchestrator enforces a minimum entry floor for the auction—
相关性和价值达不到最低线的候选
candidates that fail the minimum relevance and value bar
连竞价桌都上不去 钱多 在这里买不到通行证
aren't even allowed onto the auction table. Deep pockets alone can't buy a pass.
这是全文里我最喜欢的工程细节
This next part is my favorite engineering detail in the entire paper:
赢了竞价 广告依然可能不展示
even after winning the auction, an ad might still be dropped.
官方区分了两个事件 广告送达前端 叫delivery
OpenAI separates two events: sending the ad to the client is 'delivery',
用户真正看到 叫impression 中间隔着两道关
while rendering it to the user is 'impression'—separated by two final checks.
第一道 这条广告放在当前对话里合不合适
Check 1: Does this ad truly fit the current conversation's tone?
哪怕对话过了安全审核
Even if both the dialogue and ad passed safety filters,
广告也合规 orchestrator觉得氛围不对
if the Orchestrator judges the vibe is off,
就直接拦下 第二道 来不来得及
it blocks the ad on the spot. Check 2: Did it arrive in time?
回答生成完之前广告没到前端 本轮直接丢弃
If the ad doesn't reach the client before the chat response finishes streaming, it's dropped.
系统绝不会为了等一条广告拖慢回答
The system never slows down a chat answer to wait for an ad.
时间轴上很清楚
On the timeline, the rule is strict:
回答生成和广告流程并行
response generation and the ad pipeline run in parallel;
回答先冲线 迟到的广告作废
if the answer crosses the finish line first, any late ad is voided.
把用户体验排在广告收入前面 很多公司说过
Many companies claim they put user experience ahead of ad revenue,
用超时丢弃来兑现 是头一回有人写得这么具体
but enforcing it via hard timeout drops is a rare concrete engineering commitment.
你觉得这个超时机制能坚持几年不打折
How many years do you think this strict timeout rule will hold without compromise?
把你的判断打在公屏上
Share your prediction in the comments.
现在回答那个最敏感的问题 广告怎么不影响回答
Now let's answer the most sensitive question: how do ads avoid biasing answers?
官方架构给了两条链路
The architecture enforces two physically separate pipelines:
主链路 用户消息进来 对话模型生成回答
In the Primary Pipeline, the user message arrives and the chat model generates the answer
返回给用户 这条链路对广告系统零依赖
directly for the user, with zero dependency on the ad stack.
广告服务挂了或者变慢 回答照常
If the ad service crashes or lags, chat responses continue unaffected.
并行链路 对话上下文同步给广告系统
In the Parallel Pipeline, conversation context is synced asynchronously to the ad stack
意图分析 候选检索 资格检查 竞价
for intent analysis, retrieval, eligibility checks, auction,
最终展示检查
and final impression gating.
两边用独立的服务 独立的模型 独立的代码
Both pipelines run on separate services, separate models, and separate codebases.
还有一个值得记住的设定
And there is one foundational design principle worth remembering:
不返回广告 对这个系统来说
returning zero ads is treated by the system
是一次正常且成功的结果
as a completely normal, successful outcome.
只有对用户和广告主都明显
Only when an ad provides clear value
有价值的广告才会被放出来
to both the user and the advertiser is it ever shown.
宁可没有 写进了系统的默认行为里
'Better no ad than a bad ad' is baked into the system's default behavior.
但这里有个很关键的地方
However, there is a critical distinction here
也是很多人容易讲过头的地方
that many commentators easily overstate:
服务隔离图能证明的 是系统层面的解耦
an architecture diagram proves system-level decoupling—
广告模型确实不在回答生成的路径上
confirming the ad model isn't in the response generation path.
它证明不了的 是产品层面的长期中立
What it cannot prove is long-term product-level neutrality:
广告收入会不会影响未来的产品决策
whether ad revenue might subtly influence future product decisions,
推荐体验和功能优先级
recommendation UX, or feature prioritization.
一张架构图回答不了这个问题
No system diagram can answer that question,
目前也没有任何独立第三方审计来背书
and there is currently no independent third-party audit verifying it.
所以准确的说法有两句
So the accurate takeaway has two parts:
从公开架构看
From the published architecture,
广告不影响回答是一个有具体工程支撑的设计
response independence is backed by concrete service isolation;
商业激励的长期影响 超出公开资料能验证的范围
the long-term impact of commercial incentives remains beyond what public docs can prove.
把这两个命题混在一起 无论往哪边下结论
Conflating those two propositions—in either direction—
都不严谨
is analytically sloppy.
再往下是隐私 这里最容易被一句话带过
Next up is privacy, which is all too easy to gloss over.
对话不会给广告商 这是真的
Your raw conversations are never shared with advertisers—that part is true.
广告主拿到的是汇总的浏览量 点击量
Advertisers only receive aggregated impression and click counts,
看不到你的聊天记录 记忆和个人信息
with zero access to your chat logs, memories, or personal identity.
但这不等于对话不用于广告匹配
But that does not mean your conversation isn't used for ad targeting:
当前对话的上下文 始终参与广告选择
the current conversation context always participates in candidate selection,
如果你开了广告个性化
and if you have ad personalization enabled,
过往对话 记忆 广告互动记录也会进信号池
past conversations, memories, and ad interactions also feed into the signal pool.
数据留在ChatGPT内部做匹配 对外只出汇总统计
Your data stays inside ChatGPT for matching, while only aggregate stats leave the boundary.
这两件事要分开理解 控制入口是有的
Keep those two facts distinct. User controls do exist:
你可以关掉个性化
you can disable personalization
清除广告数据 数据最长保留30天
and clear ad history, with data retained for at most 30 days.
个人健康 心理健康 政治
Sensitive topics like physical health, mental health, and politics
这类敏感话题附近不出广告 临时聊天也不出
are excluded from ad serving, as are Temporary Chats.
另外 付费广告不代表OpenAI认可这家商家
Additionally, a sponsored placement does not imply OpenAI's endorsement,
官方写得很直白
as the official docs state plainly.
如果你是做工程的
If you're an engineer,
这篇文章里有几样东西可以直接拿走
there are five architectural patterns you can steal directly from this paper:
一 LLM做编排 确定性系统做执行
1. Use LLMs for orchestration and deterministic systems for execution—
理解 判断 调用交给模型
delegate understanding, judgment, and tool calling to the model,
钱 价格 预算交给传统系统
while keeping money, pricing, and budgets in deterministic code.
二 把选中和生效拆成两个事件
2. Decouple candidate selection ('delivery') from user rendering ('impression'),
中间加最终检查和超时机制
inserting a final vibe check and hard timeout gate in between—
这个模式在任何异步任务
a pattern that works brilliantly whenever an async sidecar task
挂到主流程的场景里都好用
attaches to a latency-sensitive main flow.
三 给每个环节记细粒度日志
3. Log fine-grained telemetry at every funnel stage—
哪一轮不适合投广告 检索有没有召回
which turn wasn't suitable for ads, whether retrieval recalled candidates,
候选挂在哪一步
and which exact filter dropped a candidate—
全部记下来 才能孤立地改进每个环节
so you can optimize each stage in isolation.
四 用最强的模型评估系统输出
4. Use your strongest frontier model to evaluate system outputs offline,
拿评估结果去训练更小的编排模型
then distill those judgments into smaller, faster orchestrator models.
五 文章结尾提到 整套系统从搭起来到跑上规模
5. As noted at the end of the post, scaling this entire system from zero to production
Codex充当了开发加速器
was heavily accelerated by Codex,
团队从一开始就把工作流建在AI编程工具上
with the team building their engineering workflow around AI coding tools from day one.
往后再看一步 9月 OpenAI测了Sponsored Agents
Looking one step ahead: in September, OpenAI began testing Sponsored Agents,
用户点进广告 可以直接和商家的Agent对话
letting users click an ad to chat directly with a merchant's custom Agent—
广告从一张卡片变成一个对话入口
turning an ad from a static card into an interactive conversational entry point.
10月 图像生成过程里开始测多图视觉广告
In October, they started testing multi-image visual ads during image generation,
效果衡量的合作方也在扩
while expanding attribution and measurement partners.
广告的形态正在从展示位变成可交互的商业体验
Ad formats are evolving from static banners into interactive commercial experiences,
这套栈的自我改进闭环 会让相关性越滚越强
and the stack's self-improving feedback loop will only compound relevance over time.
对做产品的人来说 一个信号已经很清楚
For product builders, one signal is unmistakable:
对话界面里的商业化
monetization inside conversational interfaces
游戏规则和搜索时代完全不同
operates by completely different rules than the search era.
搜索时代你买一个词
In the search era, you bought a keyword;
对话时代你进入一段持续的关系
in the conversational era, you enter an ongoing relationship.
这套广告栈真正的看点 是一种新的分工
The real highlight of this ad stack is a new division of engineering labor:
LLM负责理解和编排
LLMs handle semantic understanding and orchestration,
检索 评分 竞价这些传统组件负责执行
classic retrieval, scoring, and auction components handle deterministic execution,
独立服务和最终检查负责守住用户体验
and isolated services plus timeout gates protect the user experience.
广告系统的最高境界 是宁可不投 问题来了
The highest discipline of an ad system is knowing when not to show an ad. Now, two questions:
如果你是这个系统的工程师
If you were engineering this system,
超时丢弃的阈值你会设多少毫秒?
what millisecond threshold would you set for the timeout drop?
个性化默认开启这件事 你觉得合理吗?
And do you think enabling ad personalization by default is reasonable?
评论区聊聊 觉得这期有收获 一键三连
Let's discuss in the comments—if you found this valuable, hit like and subscribe!
我是为什么叫QQ 我们下期见
I'm WhyCallQQ—see you in the next episode.
大家好 我是为什么叫QQ
Hello everyone, I'm WhyCallQQ.
ChatGPT 的广告系统核心是一个后训练 LLM 在 agentic loop 里调用广告工具:理解多轮对话意图、生成语义查询、走 ANN 索引召回候选,经过两道资格与相关性漏斗后进入相关性加权二价拍卖,并通过最终上下文复核与超时直接丢弃机制保障主回答零延迟。